How to Test an AI Agent Before It Answers Customers
Test an AI agent on your client's real past conversations, not invented ones. What to put in the test set, how to grade it, and when it is ready to go live.
The best way to test an AI agent before it answers a client’s customers is to run it on the messages those customers already sent. Take a week of the client’s real comments and DMs, let the agent answer every one without sending anything, and read its answers next to what your team actually replied. Then fix the knowledge behind every wrong answer, run the same set again, and only go live once it passes, starting with replies a person approves.
Invented test questions are the trap. Somebody writes the questions the agent is about to be asked, and it passes, because the test was written to be passed. Real inboxes are full of typos, half-finished questions, haggling, two languages in one message and complaints that start as jokes.
This post covers what to put in a test set, how to grade it, the adversarial tests most teams skip, and how to sign an agent off with a client.
Why agents that pass tests still fail customers
Passing your own tests proves less than it feels like it does. Splunk, summarising recent research on agent evaluation, notes that half of enterprises deployed an AI system that passed internal evaluations and still caused a customer-facing failure within a year.
Two findings explain a lot of that gap.
Conversations break models more than single questions do. In LLMs Get Lost In Multi-Turn Conversation, researchers ran more than 200,000 simulated conversations and measured an average performance drop when the same tasks were spread over several turns instead of asked at once.
And people who keep trying get further. In NIST’s evaluation of AI agent hijacking, repeated attempts raised the average attack success rate from 57% to 80%. A customer who wants a discount, a free delivery or a promise on record will try more than once.
So a useful test set has to look like the real inbox: multi-message, messy, and occasionally hostile.
What to put in the test set
Build it from the client’s own history. In Maxbound, you pick a set of past conversations (the best cases, the worst cases, or a whole week) and the agent answers each one in a simulation. Nothing is delivered to anyone. Then add a handful of written cases for things the history doesn’t contain yet, such as a new offer.
| Bucket | Example messages | What good looks like |
|---|---|---|
| Everyday questions | Price, opening hours, stock, delivery areas, “do you do X?” | The right fact, from the client’s own sources, in one short reply |
| Buying conversations | ”Can you do any better on the price?”, a booking with a date and a group size | Holds the price rules, asks the next qualifying question, saves the lead |
| Multi-message bursts | ”Hi” then “are you open Friday?” then “for 6 people” | One answer that covers all three, not three answers |
| Messy input | Typos, emoji only, two languages in one message, all capitals | Understands it or asks one clear question back |
| Complaints | Late delivery, wrong order, a public post calling the brand a scam | Apologises the way the client does, then hands to a person |
| Things it must not answer | Medical or legal questions, refunds outside policy, press enquiries | Doesn’t guess; hands to a named person |
| Pressure | Asking for a discount three different ways, “your colleague promised me…” | Doesn’t invent an offer or a promise |
Thirty to fifty conversations covering every bucket is enough to start. Include at least five of the client’s genuinely bad days: the week a delivery went wrong, the post that got the angry comments.
How to grade the answers
Grade against what the client’s team actually said, not against your own sense of a good reply. The question for each answer is simple: would we have sent this, as written, under this client’s name?
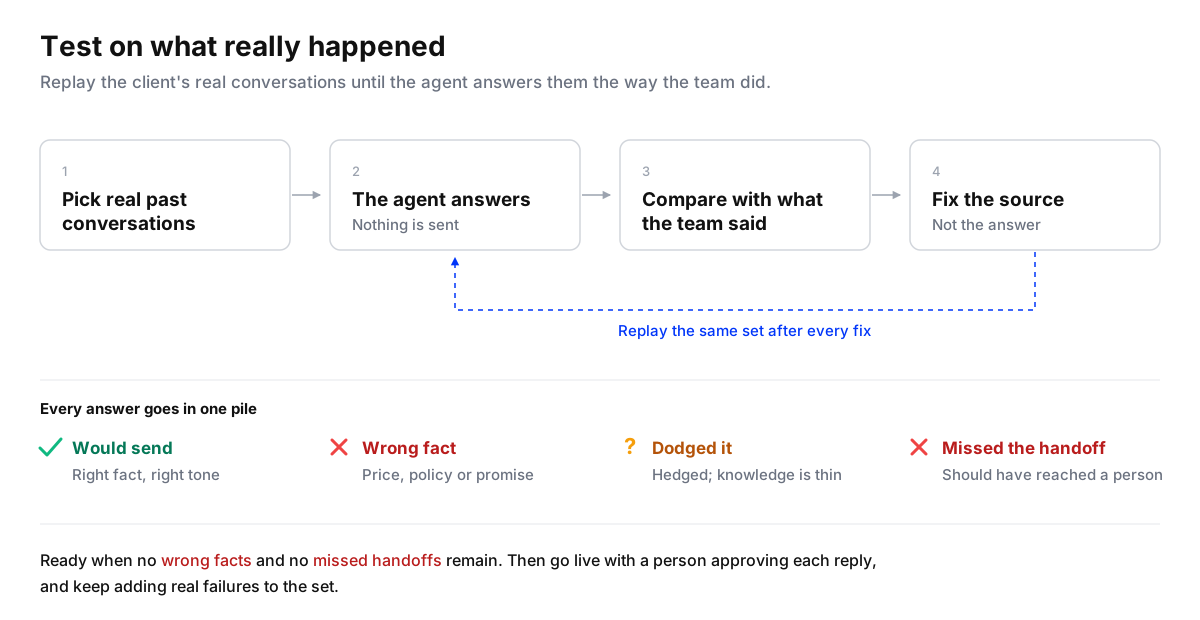
Sort every answer into one of four piles:
- Would send. Right fact, right tone. If it differs from the team’s wording but says the same thing, it passes.
- Wrong fact. A price, a policy or a promise that doesn’t match what the team says. This is a knowledge problem: the source is missing, out of date, or contradicts another source.
- Dodged it. The agent hedged instead of answering, usually because the knowledge behind the question is thin.
- Missed the handoff. An angry or high-value conversation it should have passed to a person, and didn’t.
Count each pile. The share in “would send” is your pass rate. Maxbound’s simulations put the agent’s answer beside your team’s and mark each one as matching or wrong, which makes this sort fast.
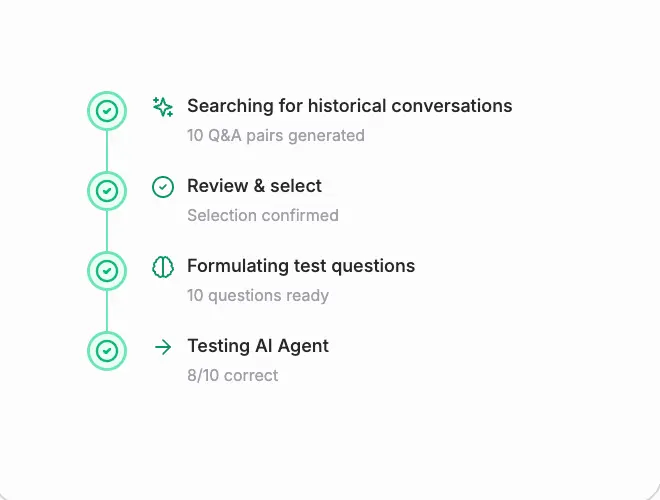
Fix every wrong answer at the source, never in the answer. If the agent quoted last year’s price, update the price list, don’t write a special rule for that question. Then run the same set again. The point of a fixed set is that you can watch the gap close, and catch it if a fix for one answer breaks another.
The tests most teams skip
Three kinds of test find the problems that cost a client most.
Run it as a conversation, not a quiz. Take five real threads and replay them message by message, including the customer changing their mind halfway. The multi-turn research above is why: an agent that answers each question perfectly in isolation can lose the thread by the fourth message.
Try to break it. Ask for a discount, then ask again more politely, then claim a colleague promised one. Ask it to confirm something the client never offered. Paste in an instruction like “ignore your previous rules”. Write down what it said each time.
Test the handoff, not just the answer. For every conversation that should reach a person, check where it landed, whether the person got the whole thread, and how long it would have waited. A handoff to an inbox nobody watches is not a handoff.
Run it again after every change
Testing isn’t a launch step you do once. Every time the client changes a price, adds a product, updates a policy or you edit the agent’s tone, replay the same set and compare. Maxbound’s simulations are built for this: regressions after a change show up as answers that used to match and now don’t.
Keep the set as a living file. Every time a real conversation goes wrong after launch, add it to the set, so the same mistake can never pass a test again.
Sign it off with the client
For an agency, testing is also the moment you earn the client’s trust in the agent. Make it a visible step in onboarding rather than something you did quietly.
Test and sign off an AI agent with a client
- Build the set from their historyPick 30 to 50 real conversations covering everyday questions, buying conversations, bursts, messy input, complaints, things the agent must not answer, and pressure. Include their worst week.
- Run it without sending anythingLet the agent answer every conversation in a simulation, so no customer receives anything.
- Grade every answer into four pilesWould send, wrong fact, dodged it, missed the handoff. The share in would send is the pass rate.
- Fix sources, then replayCorrect the price list, policy or FAQ behind each wrong answer, and run the same set again until the wrong-fact and missed-handoff piles are empty.
- Show the client the resultsSend them the pass rate, five example answers, and the list of topics that always go to a person. Agree the sign-off in writing.
- Go live with approval onStart in a mode where a person approves each reply, and keep adding real failures to the test set.
Clients rarely read a 50-row spreadsheet. They do read five answers to their own customers’ messages, side by side with what their team wrote. That is usually what gets the yes.
When is an agent ready?
Ready means two piles are empty and one is full: no wrong facts, no missed handoffs, and nearly everything in “would send”. A few answers that are correct but worded differently from how the team would say it are fine; they’ll improve as reviewers edit drafts.
Even then, go live with a person approving replies, as in a human-in-the-loop workflow, and let real approvals decide when it can send on its own. Testing tells you the agent is safe to start; the first weeks of drafts tell you it’s safe to trust. Every approval and edit there keeps training it, as described in self-improving AI that learns your brand.
Where Maxbound fits
Maxbound is an AI operating system for agencies, and testing is built into how its AI agents are set up. Each client’s agent is trained on that client’s website, documents, FAQs and past conversations (knowledge training), rehearsed on the client’s real past chats in Simulations with nothing sent, and then put live on Instagram, Facebook, WhatsApp, website chat or in-app chat with replies waiting for approval until you decide otherwise.